Jenkins can coordinate build, test and deployment tasks for data pipelines. It can trigger processing tools, but it does not replace their data-processing engines or guarantee lower costs.
Define the pipeline as code
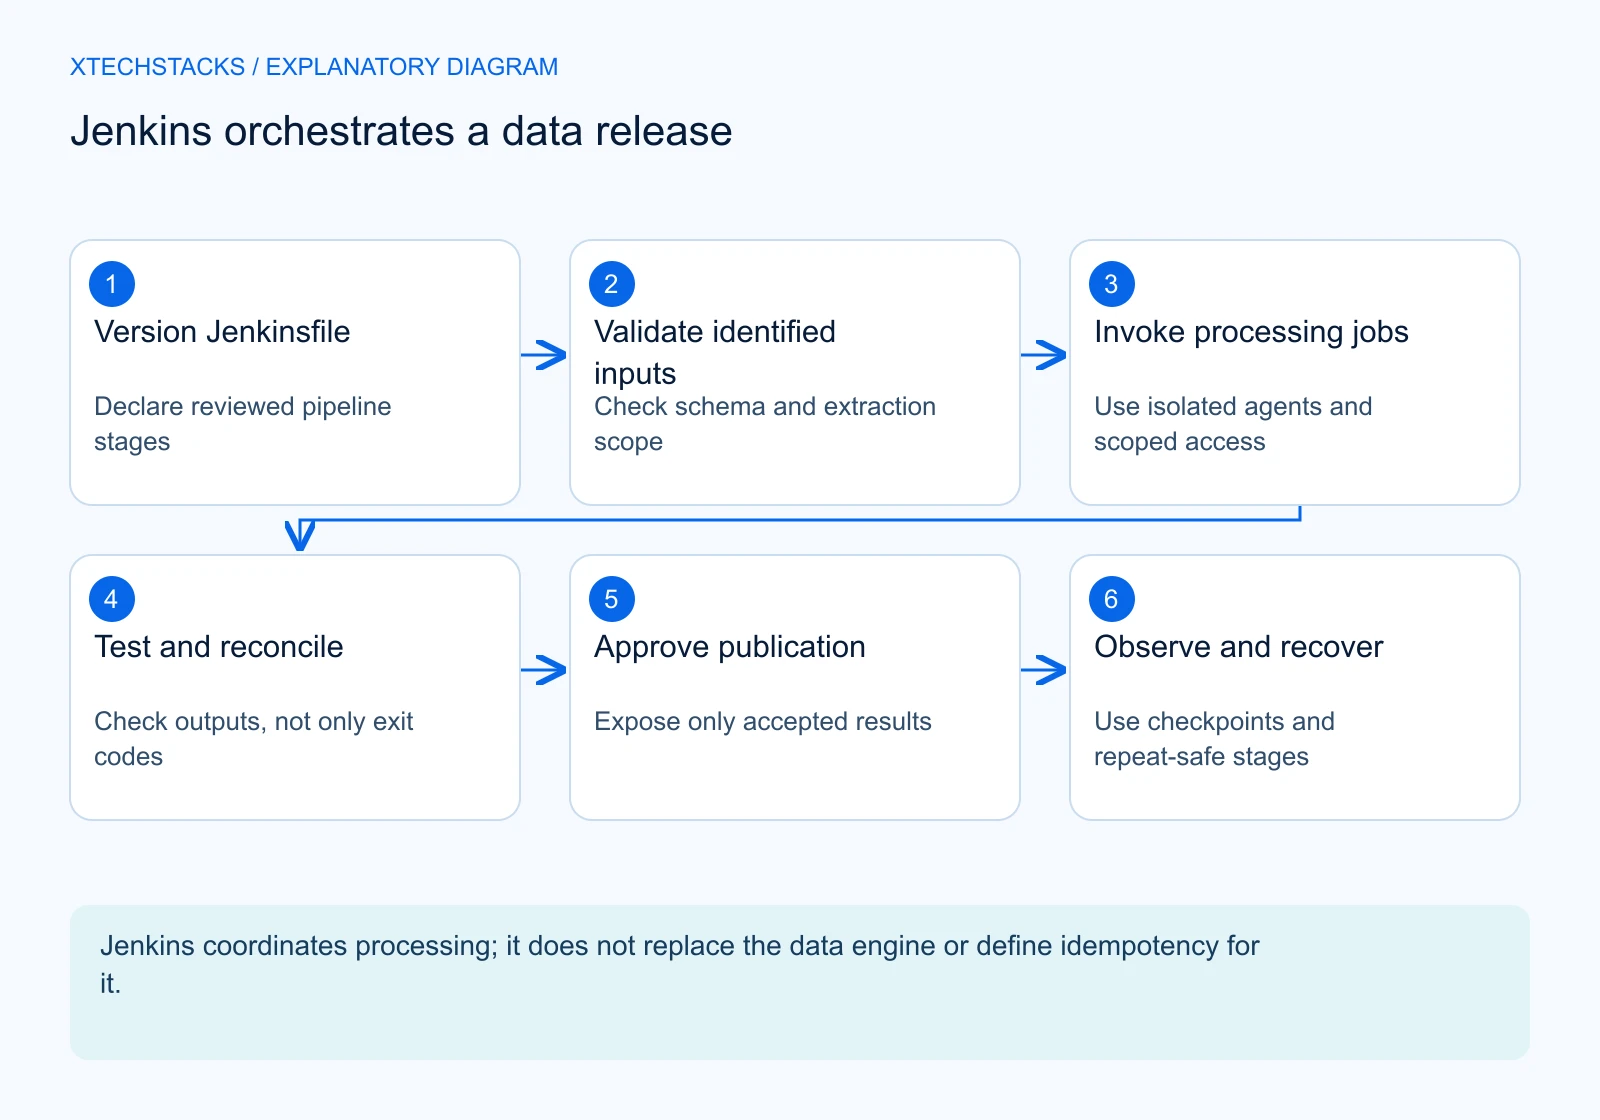
A Jenkinsfile records stages in source control. Review changes with the application and data-transformation code. Use explicit dependencies and a reproducible execution environment.
Example stages
- Validate source configuration and access.
- Trigger extraction or ingestion jobs.
- Run the chosen transformation engine.
- Check schema and data-quality results.
- Publish approved outputs and record status.
Integration controls
Limit plugin dependencies to those needed for the workflow. Protect credentials, restrict agent permissions and define timeouts and retries. A failed quality check should have a visible owner and should not silently publish invalid data.
Operating cost
An open-source license does not eliminate infrastructure, administration, plugin maintenance or incident cost. Parallel jobs may shorten execution time while increasing resource consumption. Compare the full operating cost and reliability with the existing workflow.
Monitoring
Monitor both pipeline execution and the resulting data. A successful Jenkins job does not by itself prove that downstream data is complete, timely or correct.
What Jenkins should own
Jenkins can coordinate build and delivery steps, but it should not become the hidden owner of every data-processing concern. Keep transformation logic in reviewed project code and use the pipeline to invoke defined operations. This makes local testing and migration easier than embedding all business logic in a job configuration.
A Jenkinsfile connects a reviewed source revision with its execution stages. Credentials, source intervals and artifact destinations should have explicit boundaries. The pipeline record needs enough context to explain which inputs and configuration produced an output.
A practical dataset release
Consider a hypothetical daily customer-summary dataset. A job checks out the pipeline code, validates an authorized input snapshot, runs transformations and tests a candidate output. Reconciliation verifies the intended population before the accepted output is published.
Keep publication distinct from temporary processing. If the job fails midway, consumers should not see an incomplete dataset as the latest successful result. Record the source interval, output identity and acceptance evidence independently of a green or red job badge.
Agents and execution isolation
Choose agents suitable for the required runtime and data access. Separate trusted release jobs from untrusted contributions. A job that can run arbitrary code on an agent with broad credentials creates an access boundary that must be reviewed.
Use narrowly scoped credentials and avoid revealing their values in logs, command arguments or archived files. Clean temporary sensitive data according to policy. A reusable agent is convenient, but residual workspace state can conceal missing setup or expose previous job data.
Retries, checkpoints and idempotency
Data jobs need domain-specific replay behavior. A repeated build may be harmless; a repeated database load may duplicate records. Define the unit of work, checkpoint and completion identity in the processing system rather than relying only on the scheduler’s retry count.
Before repeating an external write, establish whether the previous attempt completed. Use destination checks or an idempotent publication mechanism where appropriate. Retain failed-run evidence so operators can distinguish an input defect from an unavailable service.
Testing and release gates
Run transformation tests, source-contract checks and output validation as separate stages. Fail the release when required evidence is missing. A skipped stage should not be interpreted as a successful check simply because the remaining shell commands returned zero.
Validate schema changes and representative data cases before publication. If a source contract changes unexpectedly, stop and route the issue to its owner. Do not fix production data through an undocumented manual job rerun that changes the output’s meaning.
Operating cost and maintenance
Account for controller and agent resources, plugin maintenance, credential administration, backups and incident response. An open-source license does not make the operating system cost-free. A managed alternative may remove some work while introducing service limits or integration constraints.
Measure execution duration, failure rates, idle capacity and support effort. Compare complete operating obligations rather than promising savings from tool adoption. Retain a tested backup and restoration process for relevant job configuration and records.
Recommended approach
Use Jenkins when it fits the existing delivery architecture and the team can own it. Start with one dataset, a versioned Jenkinsfile and explicit publication controls. Avoid introducing a second orchestration platform if an existing one already supports the workload adequately.
Document the boundary between scheduling and data correctness. The best pipeline is one operators can inspect, repeat safely and recover—not the one with the most stages or integrations.
Key takeaways
- Keep processing logic independently testable.
- Separate temporary outputs from accepted publication.
- Scope agent access and make replay safe.
- Measure maintenance and operating cost honestly.
Verify a clean execution
Run the reviewed pipeline on a clean authorized agent without relying on a previous workspace. Confirm dependency setup, source retrieval and artifact publication. Compare the resulting release record with the ordinary cached run. This check can reveal undeclared files or configuration that a long-lived agent has been supplying silently.