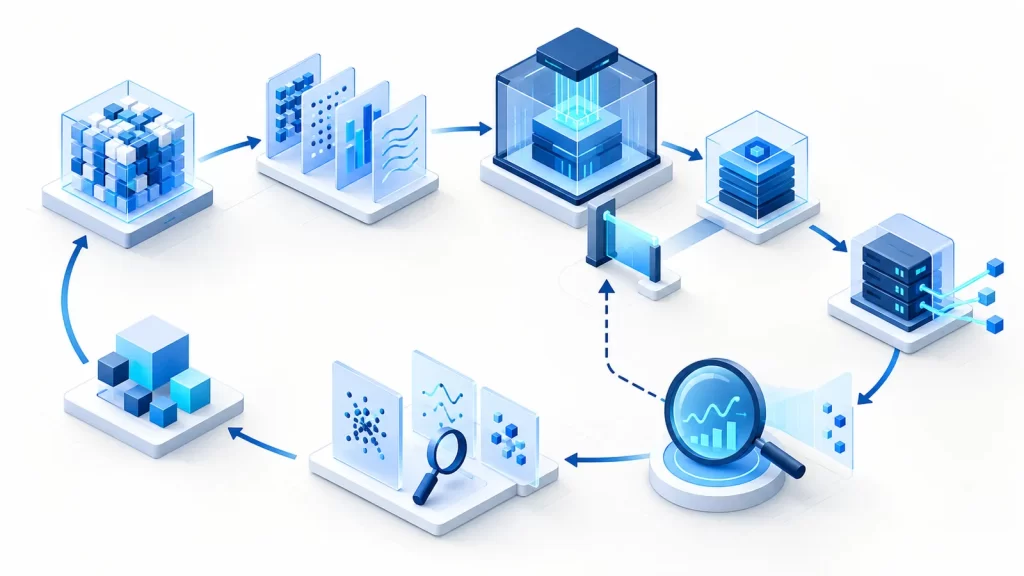
MLOps connects model development with the systems and decisions required to operate a model reliably. Training produces an artifact; production requires trusted inputs, compatible features, evaluated behavior, controlled deployment and an owner who can respond when those assumptions fail.
Thinking of MLOps only as DevOps applied to a model misses an important distinction. Software behavior changes primarily through code and configuration. Model behavior also depends on training data, evaluation choices and the population encountered after deployment. The lifecycle must make those dependencies visible.
The lifecycle is a connected system
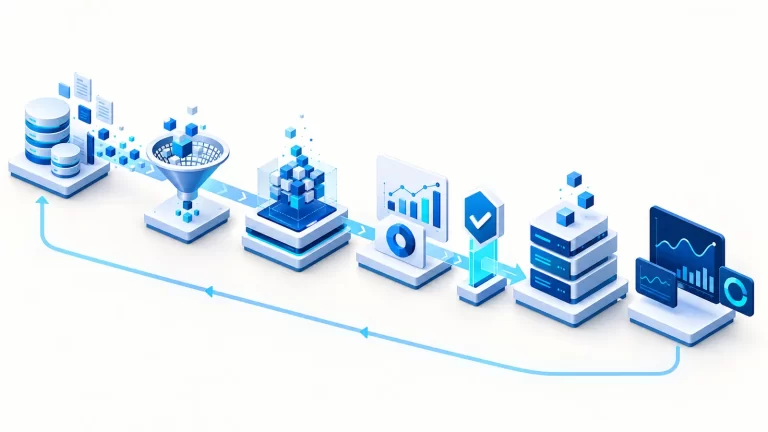
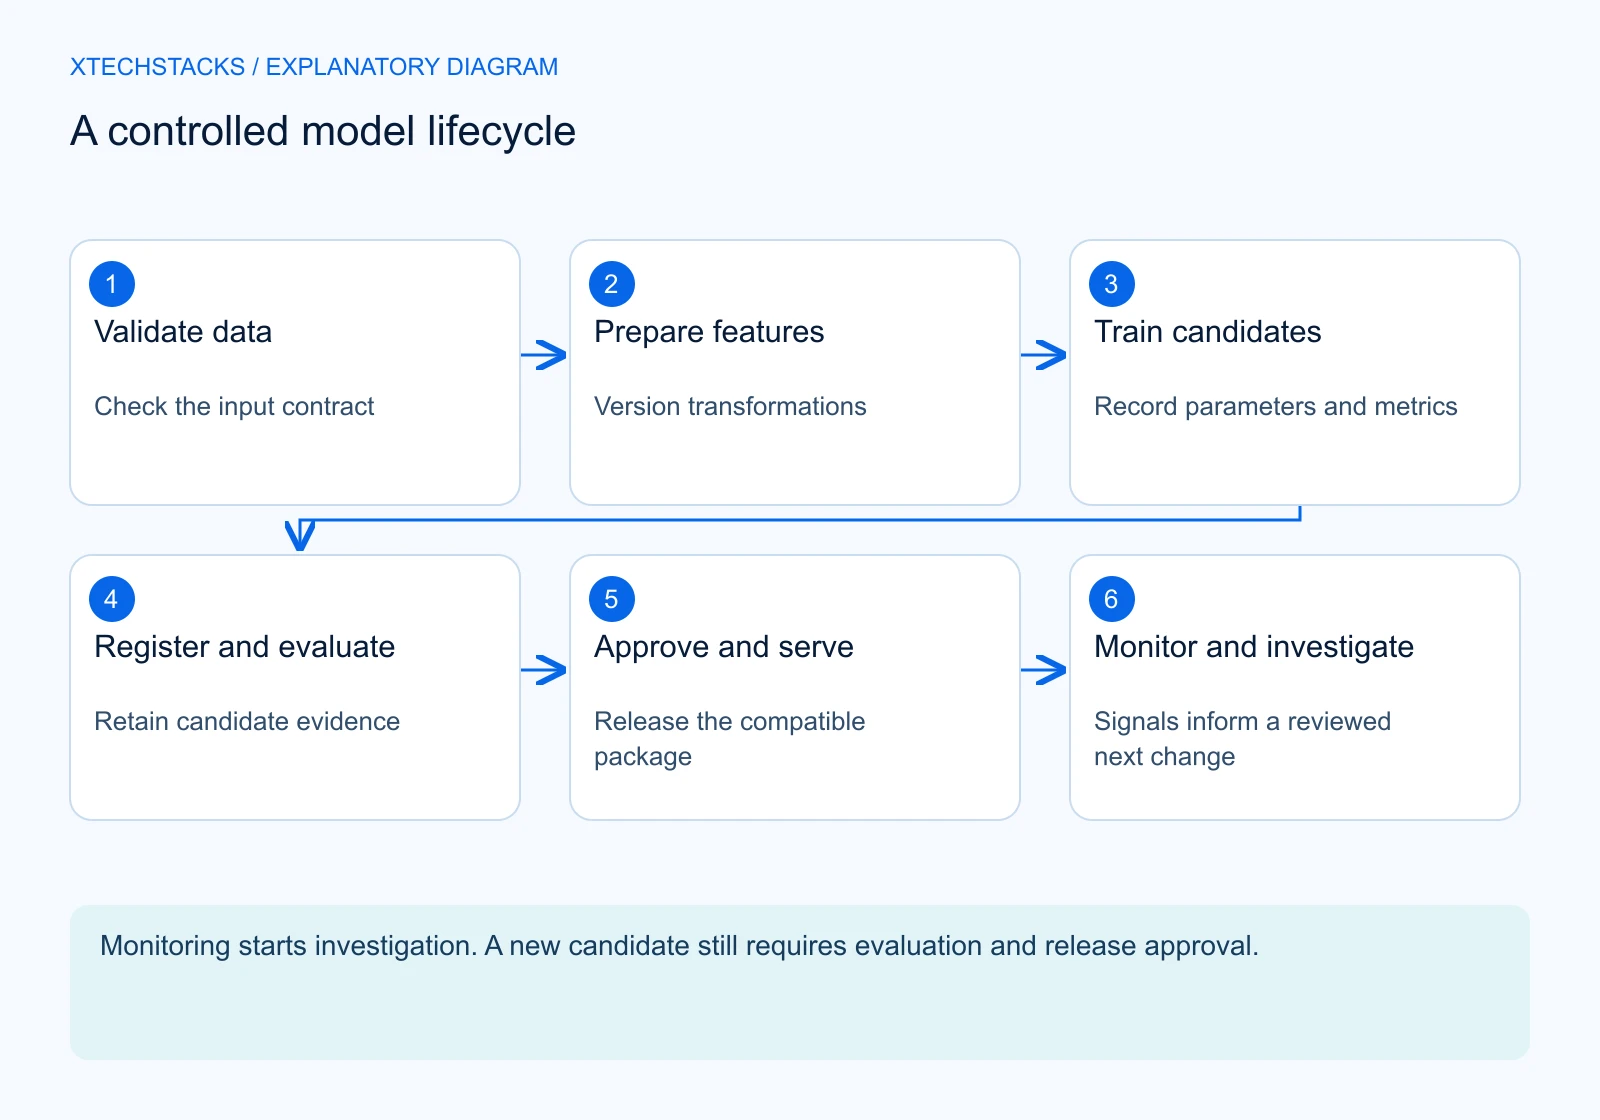
A practical lifecycle runs from data ingestion and validation through feature preparation, training, experiment tracking, registration, deployment and monitoring. Feedback can lead to investigation and controlled retraining. These stages are connected through recorded versions and approval gates, not simply arranged as boxes on a diagram.
Assign an owner to each boundary. Data engineering may own ingestion contracts; model developers may own training and evaluation; platform engineers may own execution and serving. Product or domain owners must help define acceptable behavior. Organizational names vary, but ambiguous ownership is a recurring operational risk.
Data ingestion and feature preparation
Capture the source, collection window, schema and permitted use of training data. Validate missing values, unexpected categories, duplication and quality conditions relevant to the task. A pipeline that runs successfully can still consume unsuitable data. Keep source validation separate from model-quality evaluation.
Features need reproducible definitions and consistent behavior between training and inference. Differences in timestamps, aggregation windows or missing-value rules can create training-serving skew. A feature store can help when multiple teams need shared, governed features, but a small workload may be better served by a tested transformation library and explicit snapshots.
Training and experiment tracking
Move important training logic from exploratory notebooks into repeatable jobs. Record code, data references, feature definitions, parameters, dependency versions and generated artifacts. Preserve enough information to compare experiments without relying on an engineer’s memory or a local folder name.
Split data according to the problem, including time or entity boundaries when necessary to prevent leakage. Use representative evaluation cases and inspect relevant segments rather than selecting a candidate solely on one overall score. An experiment tracker organizes evidence; it does not determine whether the evidence is sufficient for release.
Registration and release validation
A model registry gives an artifact a managed identity and can support release status or approval workflows. Associate that identity with the experiment, input schema, dependencies and evaluation report. Do not assume the registry also versions every upstream dataset or feature transformation.
Before promotion, validate the complete serving package. Test loading the artifact, preprocessing an input, producing the expected output shape and handling invalid requests. Add security, compatibility and resource checks appropriate to the workload. A container is a useful packaging mechanism, not proof of reproducibility or acceptable predictions.
CI, CD and continuous training
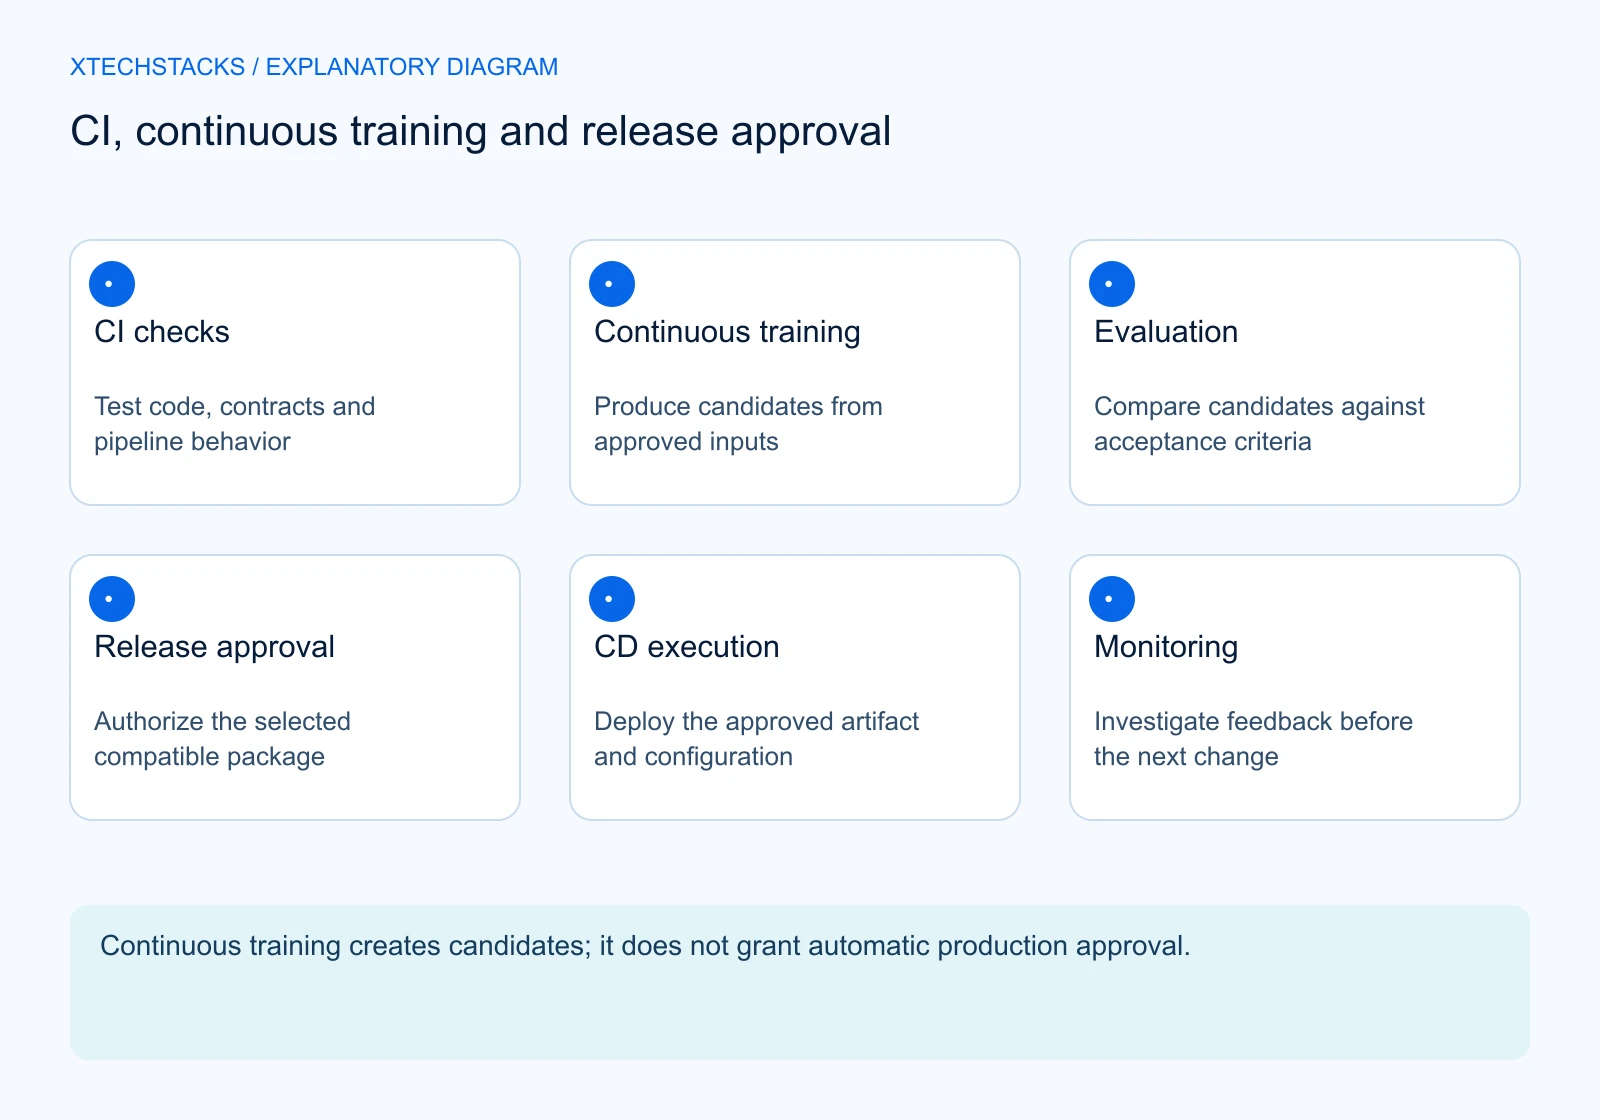
Continuous integration checks changes to code, transformations and pipeline definitions. Continuous delivery moves an approved package through controlled environments. Continuous training automates parts of candidate generation when suitable data or a justified trigger is available. These capabilities should not be confused with automatically approving every new model.
Use explicit gates between candidate creation and production promotion. A scheduled retraining job may produce a worse candidate, fail a segment-level test or consume an invalid source. The safe default is to preserve the currently approved release until a replacement satisfies its acceptance criteria.
Deployment patterns and operational controls
Choose batch, online or edge inference around the application. Batch scoring emphasizes job completion, data freshness and reconciliation. Online serving adds latency, availability and request-validation requirements. Edge delivery introduces device compatibility and update constraints. Avoid deploying an API merely because it is familiar when a scheduled output would satisfy the use case.
Introduce a candidate gradually when the system supports it. Shadow evaluation can compare behavior without exposing candidate decisions to users. Canary releases limit exposure, but require an observable acceptance decision and a workable rollback. Store the previous approved artifact and its serving configuration together.
A practical example: a support-ticket classifier
In a hypothetical classifier, ingestion validates an approved ticket snapshot. Preparation removes prohibited fields and creates versioned features. Training records parameters and produces a candidate. Evaluation compares routing accuracy and unsupported cases against a fixed set. The registry records the accepted artifact and the deployment pipeline promotes that exact package.
Production monitoring tracks failed requests, response latency, class distributions and reviewed routing outcomes. A changed ticket vocabulary triggers investigation, not automatic retraining. The team first checks ingestion and preprocessing, then evaluates whether new labeled data and a new model are warranted. This sequence avoids using a model update to conceal a data-contract defect.
Monitoring, feedback and governance
Service health and prediction quality are different signals. Healthy infrastructure does not prove good decisions. Drift signals describe changes in observed distributions; they are not conclusive evidence of quality degradation. Where labels arrive later, record that delay and avoid presenting immediate proxies as measured accuracy.
Maintain access controls, lineage, retention policies and a documented approval trail. Capture relevant feedback with appropriate permissions and review it before incorporating it into training. Define who can stop a release, investigate an incident and authorize a replacement. Governance is most useful when it is built into ordinary engineering workflows.
Recommended approach and takeaways
Start with one model, a reproducible package, a representative evaluation set and an accountable production owner. Add automation where it removes a known failure mode. A large catalog of tools is not a substitute for reliable boundaries.
- Connect the entire lifecycle through versioned evidence.
- Keep training, evaluation and release approval distinct.
- Monitor both service operation and task behavior.
- Investigate before retraining, and retain a tested rollback path.