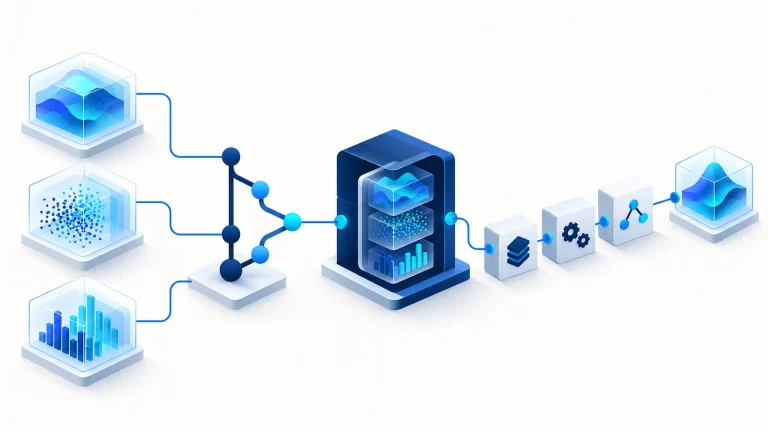
An ETL service extracts data from a source, applies defined transformations and loads the result into a destination. A SaaS implementation also needs tenant isolation, access controls and clear operational ownership.
Requirements and architecture
Define supported sources, destinations, data volumes and transformation rules. Angular can provide the interface; backend services should handle connectors and processing. AWS services such as S3, Glue and Redshift may serve different storage and processing roles depending on requirements.
Interface and authentication
Let users configure connections, transformations and schedules without exposing stored credentials. Authentication alone is insufficient: authorize each request against the tenant and resource it is allowed to access.
Processing workflow
- Validate the source connection and extraction configuration.
- Read data within the approved scope.
- Apply tested transformations and validate the result.
- Load data with defined retry and duplicate-handling behavior.
- Record status, failures and lineage for investigation.
AI assistance
An AI component may draft SQL or suggest transformations. Treat generated instructions as untrusted proposals. Validate them before execution and require review for changes that could overwrite or expose data.
Testing and operations
Test connectors, transformation correctness, tenant boundaries, failure recovery and load. Pin and test supported Angular and backend dependency versions. Monitor service health and define retention and deletion behavior.
Separate the control plane from processing
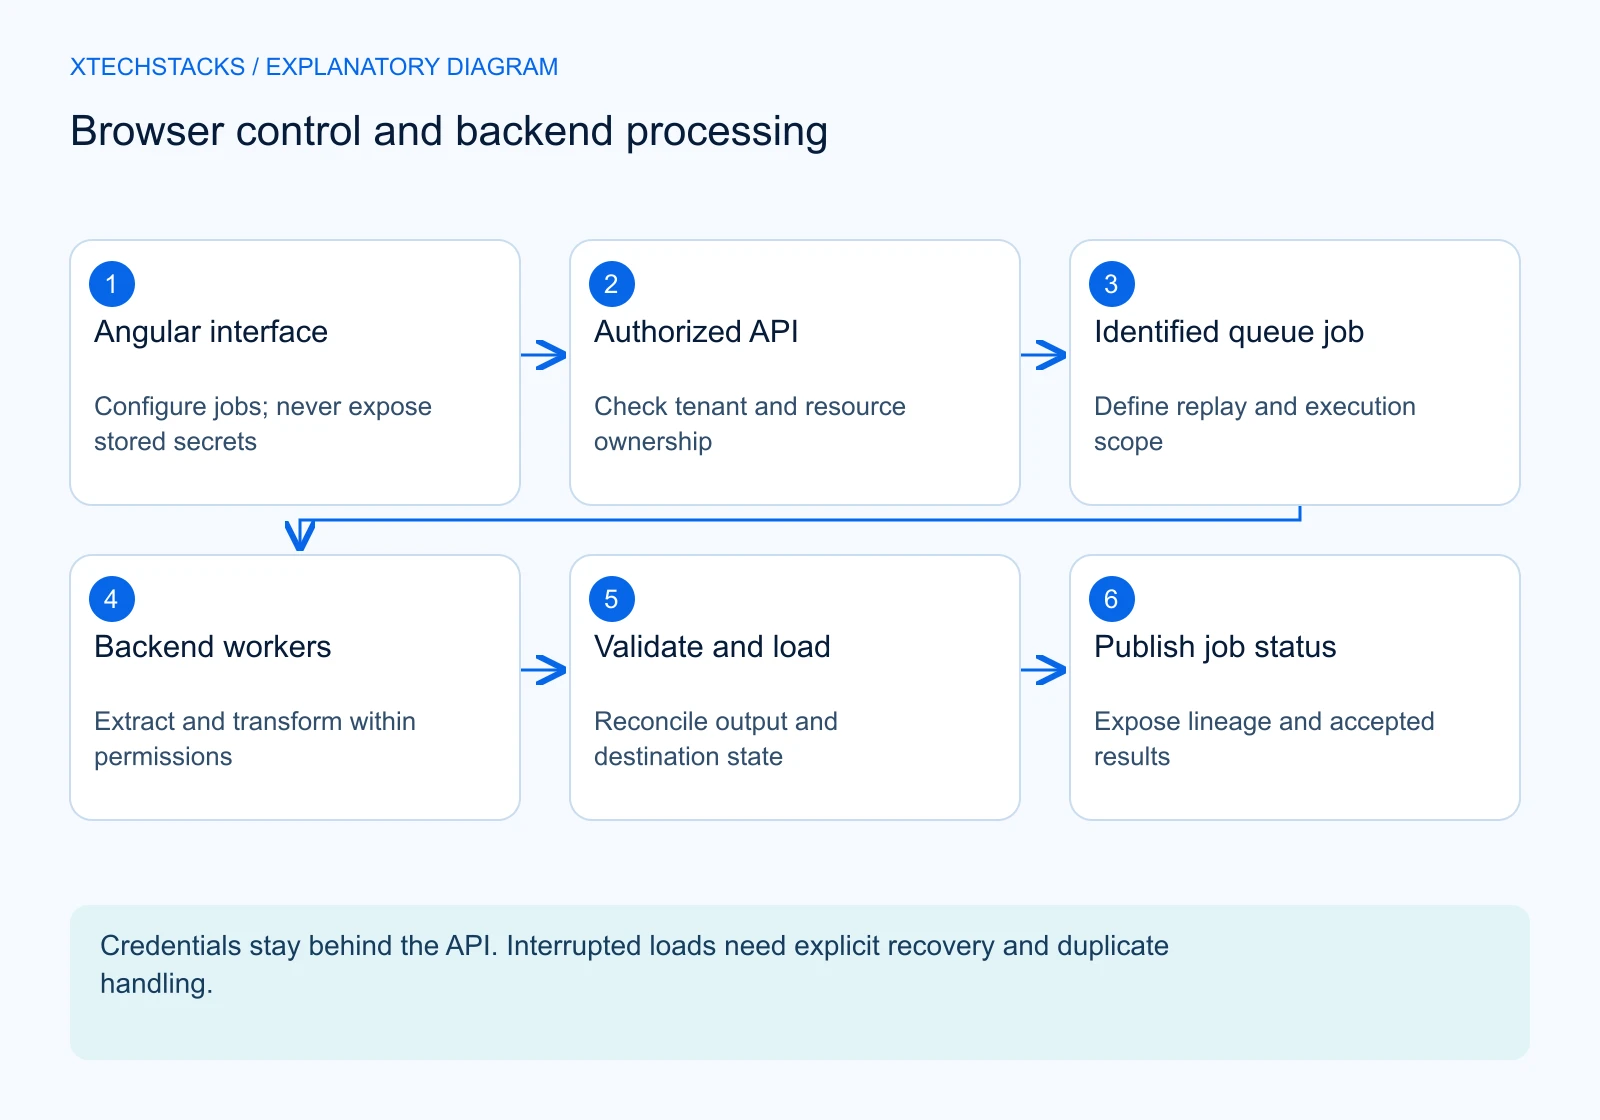
An Angular interface should configure jobs, display status and support authorized user actions. It should not hold source credentials or execute long-running ETL logic in the browser. A backend control plane validates configuration and starts processing through a defined execution boundary.
For a hypothetical multi-tenant import service, the interface submits a source definition and mapping. The backend checks tenant ownership and permitted destinations. A worker processes an identified input and records its result. Each boundary should have a stable request and job identity.
Tenant isolation and credentials
Every source, job, artifact and destination needs a tenant association enforced by the backend. A tenant identifier provided by the browser is not sufficient authorization. Test requests that reference another tenant’s job or output directly.
Store source credentials in the existing protected secret mechanism and grant workers only the required access. Avoid returning secrets to the interface or placing them in logs. Define revocation behavior when a connector is disabled or a customer removes access.
Connector and schema contracts
Each connector should specify supported extraction semantics, pagination, rate limits and update behavior. A source file and a changing application API require different replay assumptions. Record checkpoints and the population represented by an extraction.
Validate mappings and transformations before loading. Unexpected fields, invalid values and incompatible destination schemas should produce inspectable failures. Do not silently coerce every error into a default value that makes the job appear successful.
Queues and worker execution
A queue decouples submission from execution, but the worker must handle duplicate delivery and failures deliberately. Use stable job identities and idempotent stages where appropriate. A timeout does not establish that a downstream write failed.
Apply resource and concurrency limits so one tenant cannot exhaust shared capacity. Record stage-level status, attempt history and useful error details. Keep customer-sensitive records out of generic diagnostics and expose only information the requesting tenant may access.
A practical load sequence
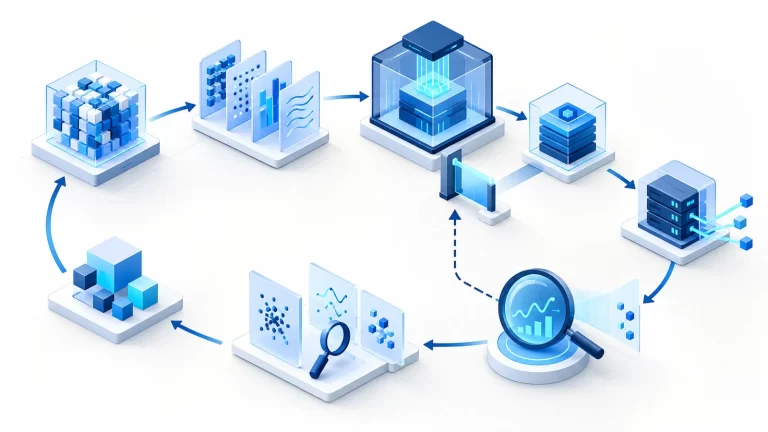
The import example captures an input snapshot, validates the mapping and writes a candidate destination batch. Reconciliation checks expected records and relevant totals. An acceptance step exposes the completed result and records its lineage.
If the load is partial, the system needs a defined cleanup, resume or replacement strategy. Avoid telling the user merely to press retry without knowing which destination records already changed. A recoverable data workflow is part of the product contract.
Monitoring and customer visibility
Show queued, running, failed and accepted states with meaningful timestamps. Distinguish a completed worker from an accepted dataset. Provide freshness and reconciliation information when it affects downstream use.
Operators need cross-system telemetry, but customer access remains tenant-scoped. Establish support procedures that do not require broad exposure of customer credentials or data. Track failure patterns to improve connector behavior and documentation.
Trade-offs and implementation sequence
Managed AWS services can reduce infrastructure work while adding service-specific limits and configuration responsibilities. Select execution, storage and orchestration around the job duration and data characteristics. Do not promise unlimited scale from a collection of service names.
Begin with one connector, one destination and one tested replay path. Add transformations only when their semantics and recovery behavior are clear. A smaller ETL product with reliable tenancy and reconciliation is more useful than many connectors with ambiguous correctness.
Key takeaways
- Keep browser interaction separate from credentials and processing.
- Enforce tenant ownership at every backend boundary.
- Design replay around destination state.
- Publish accepted outputs with clear lineage.
Test an interrupted load
Stop a controlled worker after a partial destination write. Inspect the recorded job state and repeat the same identified input. Verify that the recovery procedure either resumes safely or replaces the partial output without duplicating accepted records. Include this check in connector acceptance rather than waiting for the first customer incident.