Generative AI can help engineers organize operational information. It should complement observability and incident processes, not be assumed to detect every failure or determine root cause correctly.
Log summarization
Summaries can reduce the effort of reading related events. Preserve links to source logs and timestamps so that an engineer can verify the summary. Redact secrets and sensitive data before sending logs to a model.
Incident report drafts
A draft may assemble the timeline, affected components and observed symptoms. Keep confirmed facts separate from hypotheses. Suggested causes or remediation steps require validation by the incident owner.
Alert triage
AI assistance may group or explain alerts, but should not silently suppress critical signals. Define escalation rules and measure missed incidents as well as reduced noise. Keep conventional monitoring and alert delivery in place.
Prediction and model updates
Predicting outages requires task-specific evidence and evaluation; text generation alone does not establish forecasting capability. Hosted models do not necessarily learn continuously from new logs. Update prompts, knowledge and models through a controlled change process.
Evaluate a bounded pilot
- Use incidents with known timelines and outcomes.
- Measure factual accuracy and omitted events.
- Compare review effort and response time against a baseline.
- Test access controls and failure behavior.
- Retain human approval for consequential operational actions.
Keep telemetry as the evidence layer
Logs, metrics and traces have different roles. Metrics describe measured behavior over time; logs preserve event details; traces connect work across request boundaries. A generated incident summary should refer to this evidence rather than replace it with an unverifiable narrative.
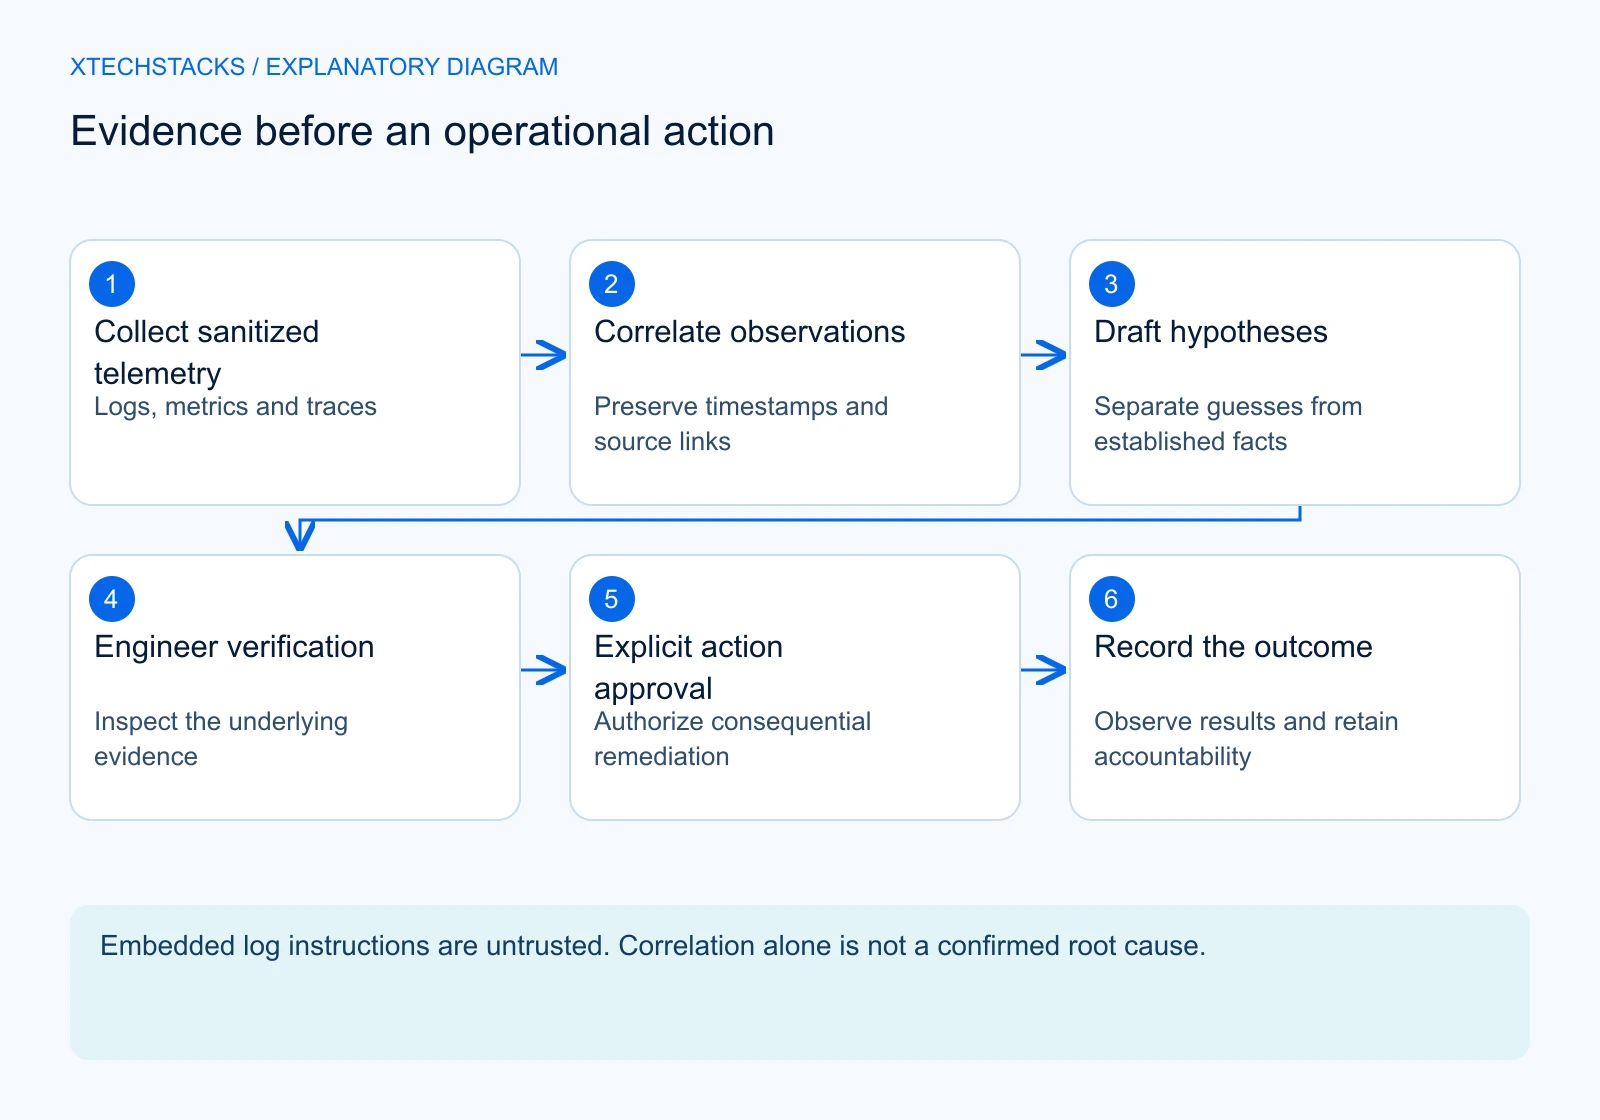
For a hypothetical service-latency incident, collect the relevant time window, affected services and release identities. Supply selected evidence with clear source references. The model can propose a concise summary, but an operator must distinguish observations from possible causes.
Separate correlation from diagnosis
Two events occurring together do not establish causation. A deployment near a latency increase is a useful investigation lead, not proof that the deployment caused it. Generated explanations should label hypotheses and preserve contradictory evidence.
Use deterministic correlation and existing observability queries where they provide reliable structure. A language model can help organize the result for review. Do not allow fluent wording to turn incomplete telemetry into an authoritative root-cause statement.
Incident drafts and communication
A draft should identify confirmed impact, time window, current mitigation and unresolved questions. Avoid inventing customer counts or service-restoration estimates. Keep internal diagnostic detail separate from external communication that requires review.
Store the reviewed incident record and its supporting evidence. Corrections should be traceable. An automatically produced summary can be useful, but it should not silently overwrite the operator’s account of what actually occurred.
Data access and prompt boundaries
Telemetry can include credentials, personal information and confidential infrastructure details. Limit the material sent to a provider and define retention and trace access. Redaction mechanisms need testing rather than an assumption that logs are safe because they are technical.
Treat log messages and retrieved runbooks as untrusted text. An attacker-controlled request may appear in a log and attempt to redirect the assistant. Application permissions must not change because a telemetry record contains instructions.
Actions require explicit control
Restarting a service, changing a configuration or rolling back a release affects operating systems. Keep these actions behind existing access checks and approval requirements. Validate target identities and proposed arguments in ordinary code.
Start with read-only assistance. If action support is later added, define a bounded catalog and a destination-state check before retries. A lost response does not prove that an action failed. Record the actual system result separately from the generated explanation.
Evaluation and operational limits
Use historical incidents with permission and appropriate sanitization to test summaries, missing evidence and incorrect hypotheses. Evaluate usefulness to operators, factual grounding and dangerous suggestions. Measure review effort rather than assuming that automation always speeds recovery.
Test provider outages and incomplete telemetry. The established incident process should continue without the model. An assistance layer that blocks access to ordinary dashboards or runbooks creates a new failure mode during the moment they are most needed.
Recommended approach
Begin with evidence-linked draft summaries for one incident type. Keep diagnosis and mitigation human-controlled. Add broader correlation only when its false-positive behavior is understood and operators can inspect the underlying evidence.
Expand based on observed quality and clear operating ownership. Generated incident language is useful when it improves shared understanding; it is harmful when it conceals uncertainty or turns speculation into automated action.
Key takeaways
- Preserve telemetry references and release context.
- Label hypotheses separately from observations.
- Protect sensitive logs and ignore embedded instructions.
- Keep consequential remediation behind explicit controls.
Test uncertainty in a summary
Provide a sanitized incident window containing a deployment event and a latency increase without evidence connecting them. Verify that the draft identifies correlation as a hypothesis, links the observations and does not invent a root cause. An operator should be able to inspect the evidence without accepting the model’s proposed explanation.